Bitcoin Price and OpenAI GPT-5 Pricing: What the Mixed Search Means
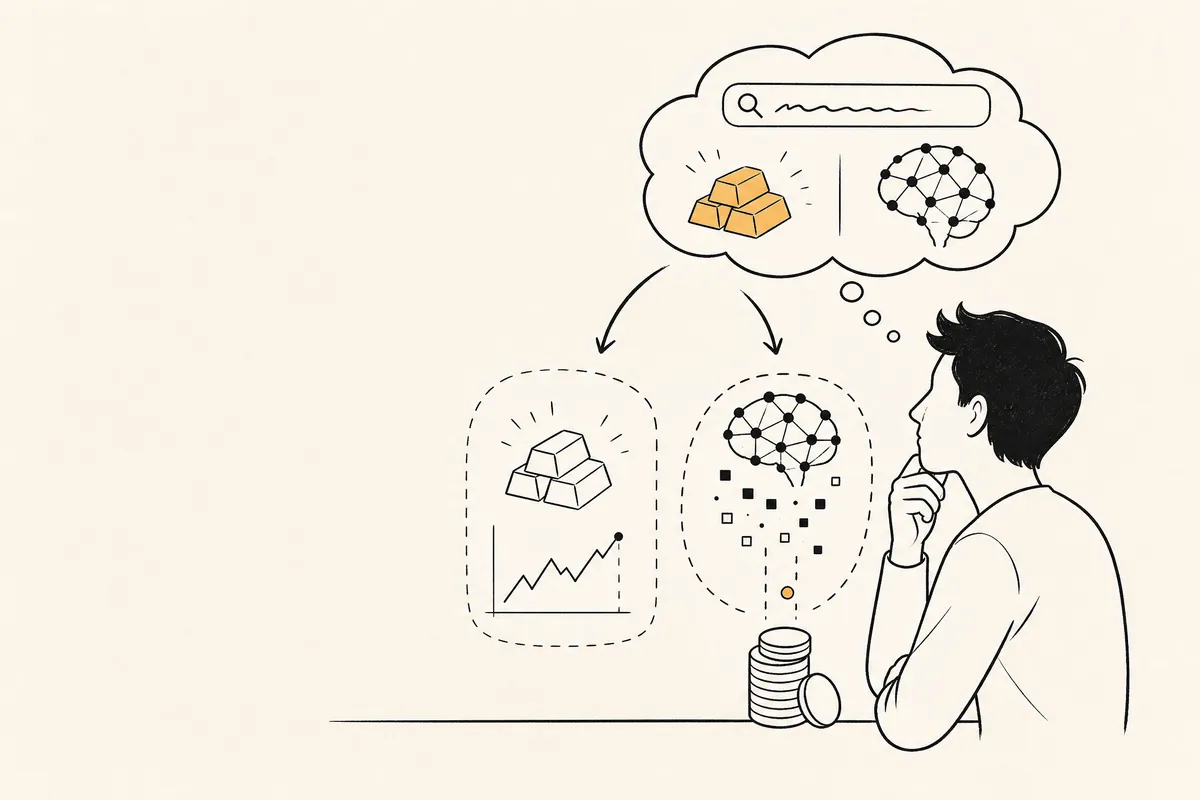
Bitcoin has a changing market price, while GPT-5 has API token rates. Understand the difference and calculate a GPT-5 bill without confusing it with live crypto data.
Practical guides for using AI APIs in production, from model selection and integration patterns to pricing, reliability, and workflow design.

Bitcoin has a changing market price, while GPT-5 has API token rates. Understand the difference and calculate a GPT-5 bill without confusing it with live crypto data.

GLM-5.3-Prime is a GLM-family model listed for token-based API access. See its catalog specifications, current price row, and an actual first response.

Codevolve’s documented integrations concern browser coding labs and learning platforms. Check the MindTap announcement, LTI submission behavior, and current support before migrating.

Understand Alibaba’s Qwen3.7 Plus, its context-based token pricing, and how to send a verified API request with the exact model ID.

Compare Gemini 2.5 Flash input, output, and cached-token prices, estimate a request budget, and make an OpenAI-compatible call with Python, Node.js, or cURL.

Connect Claude Code Router to a Zhipu-compatible provider without mixing keys, billing plans, or API protocols. Check the route before trusting an agent workflow.

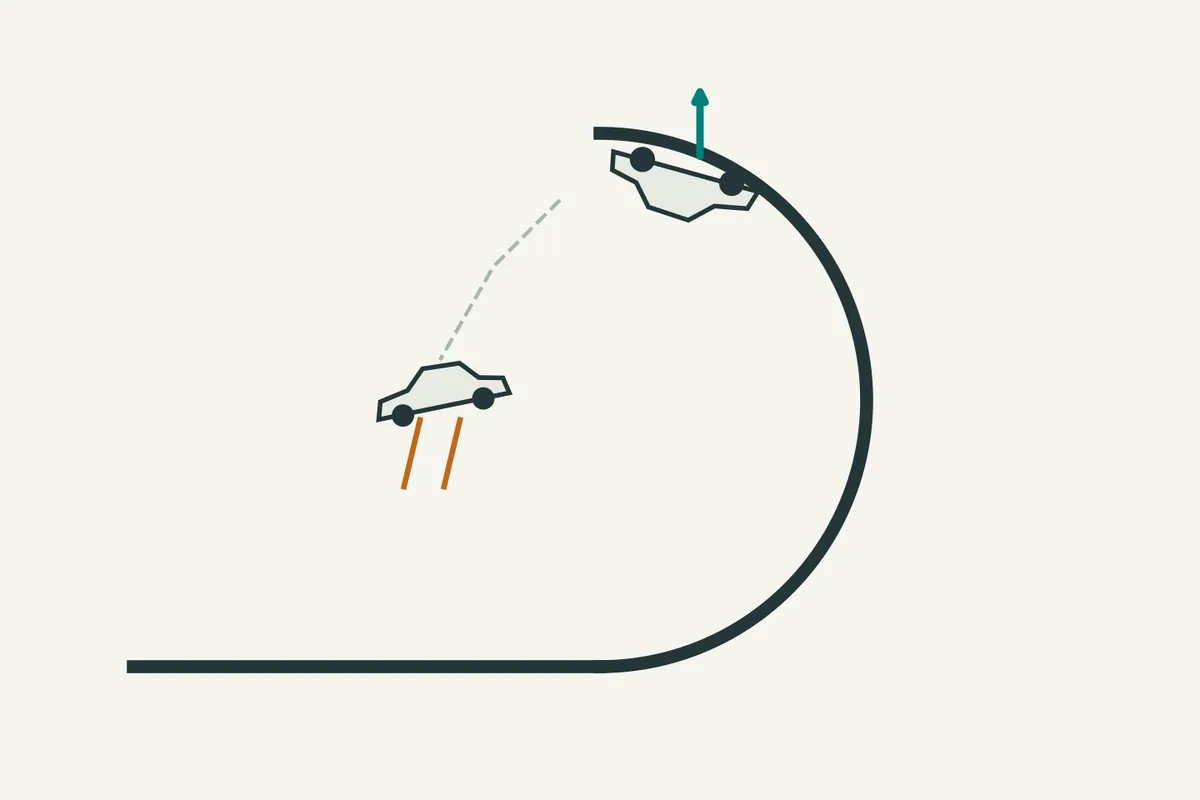
How can Tesla’s new Roadster remain nearly upside down on a reverse-C ramp about 21 meters high, then leave the track, flip, and land gently? Drawing on reports of the October 2026 unveiling, interactive animations and force calculations explain fan-generated suction, tire friction, cold-gas propulsion, and attitude control, while distinguishing demo readings from teaching assumptions.

Separate the mixed search phrase from actual GPT-5 API prices, estimate token costs, and understand why a model response is not a live gold quote.

Understand Nano Banana 2 image billing, send a minimal API request, and handle returned images without confusing gateway aliases or subscription plans.

Find Claude pricing on Google Cloud, separate input and output charges, and compare a reference Vertex rate with a gateway rate without mixing billing products.

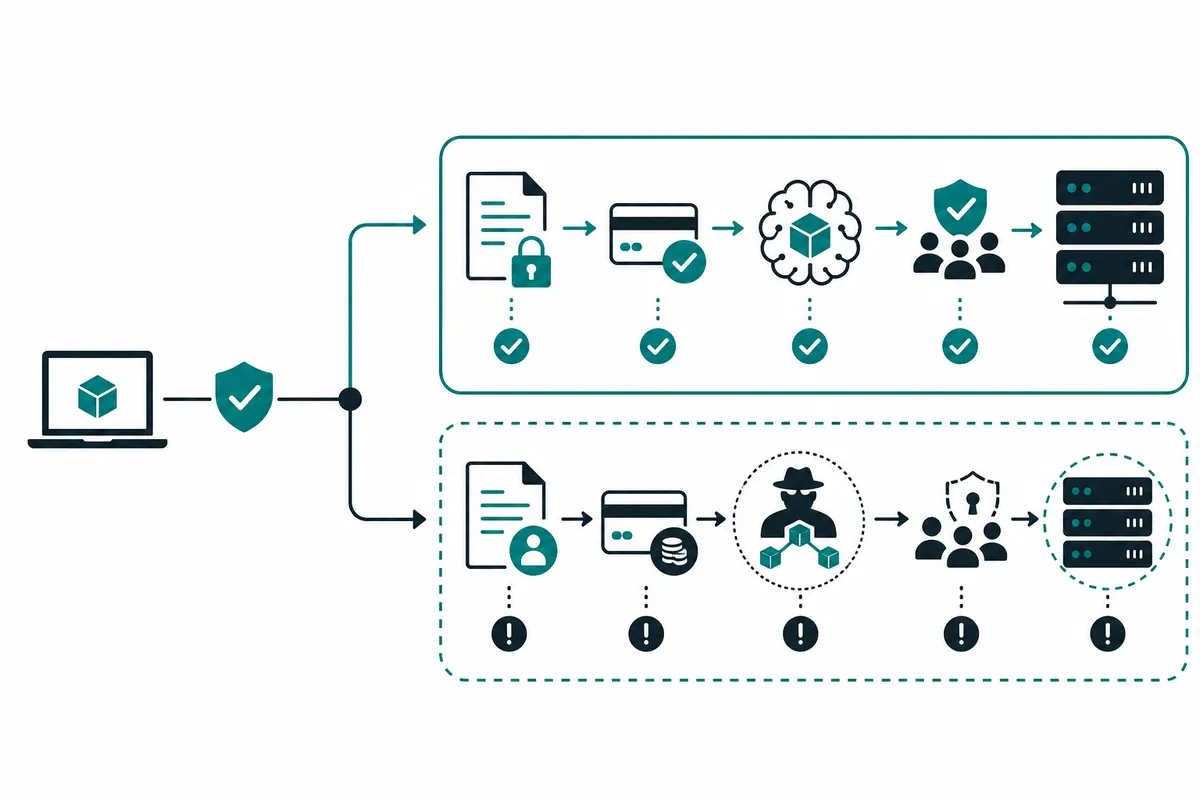
Compare official APIs and resellers by data handling, billing, model identity, and access controls before sending production requests.

Choose between official provider compatibility endpoints and one shared gateway endpoint for Claude and Gemini, with tested request patterns and clear credential boundaries.

Separate chatbot availability from developer API access in Hong Kong, and check current provider eligibility before relying on a free option.

Gemini 3 Pro Preview is shut down on Google's API. Separate that retired identifier from Gemini 3.1 Pro and compare current token rates correctly.

Use a model gateway to share one key across supported providers, without confusing a common endpoint with universal model access.

Choose a Claude API billing route, check account-specific credits, and budget development with measured token usage instead of chat-subscription assumptions.

Check regional eligibility, create the right developer key, and distinguish direct Claude access from a gateway account before writing code.

Build a resumable incremental embedding index in Python and SQLite. Deduplicate text, checkpoint vectors, publish atomic updates, and handle deletions safely.

Diagnose Claude prompt-cache misses using real cache-write and cache-read token counts. Reproduce a controlled test and separate prefix issues from routing hypotheses.

DeepSeek V4 Pro costs $1.32 per 1M input tokens and $3.96 per 1M output tokens direct, while Crazyrouter lists $1.34 and $4.00. Use the exact model ID with these cURL, Python, and Node.js examples.

GPT-5 costs $1.25 per 1M input tokens, $0.125 per 1M cached input tokens, and $10 per 1M output tokens at list price. This guide calculates real workloads and shows a working API call.
Claude Haiku 5.5 is cheaper and supports a larger context than Haiku 4.5. Six real API calls show how both models handle arithmetic, JSON extraction, and Python generation.

Claude Haiku 5.5 is Anthropic's fastest current model for high-volume extraction, classification, and routing. This guide covers its verified specs, tiered price, and working API examples.
Read Claude pricing on Bedrock by model and token type, calculate a workload estimate, and avoid confusing standard rates with caching or provisioned capacity.
We ran the same three prompts through both image routes, inspected all six files, and compared latency, prompt compliance, billing, and integration behavior.

Understand the Nano Banana 2.1 image route, its published billing unit, and the exact request that returned an image in our October test.

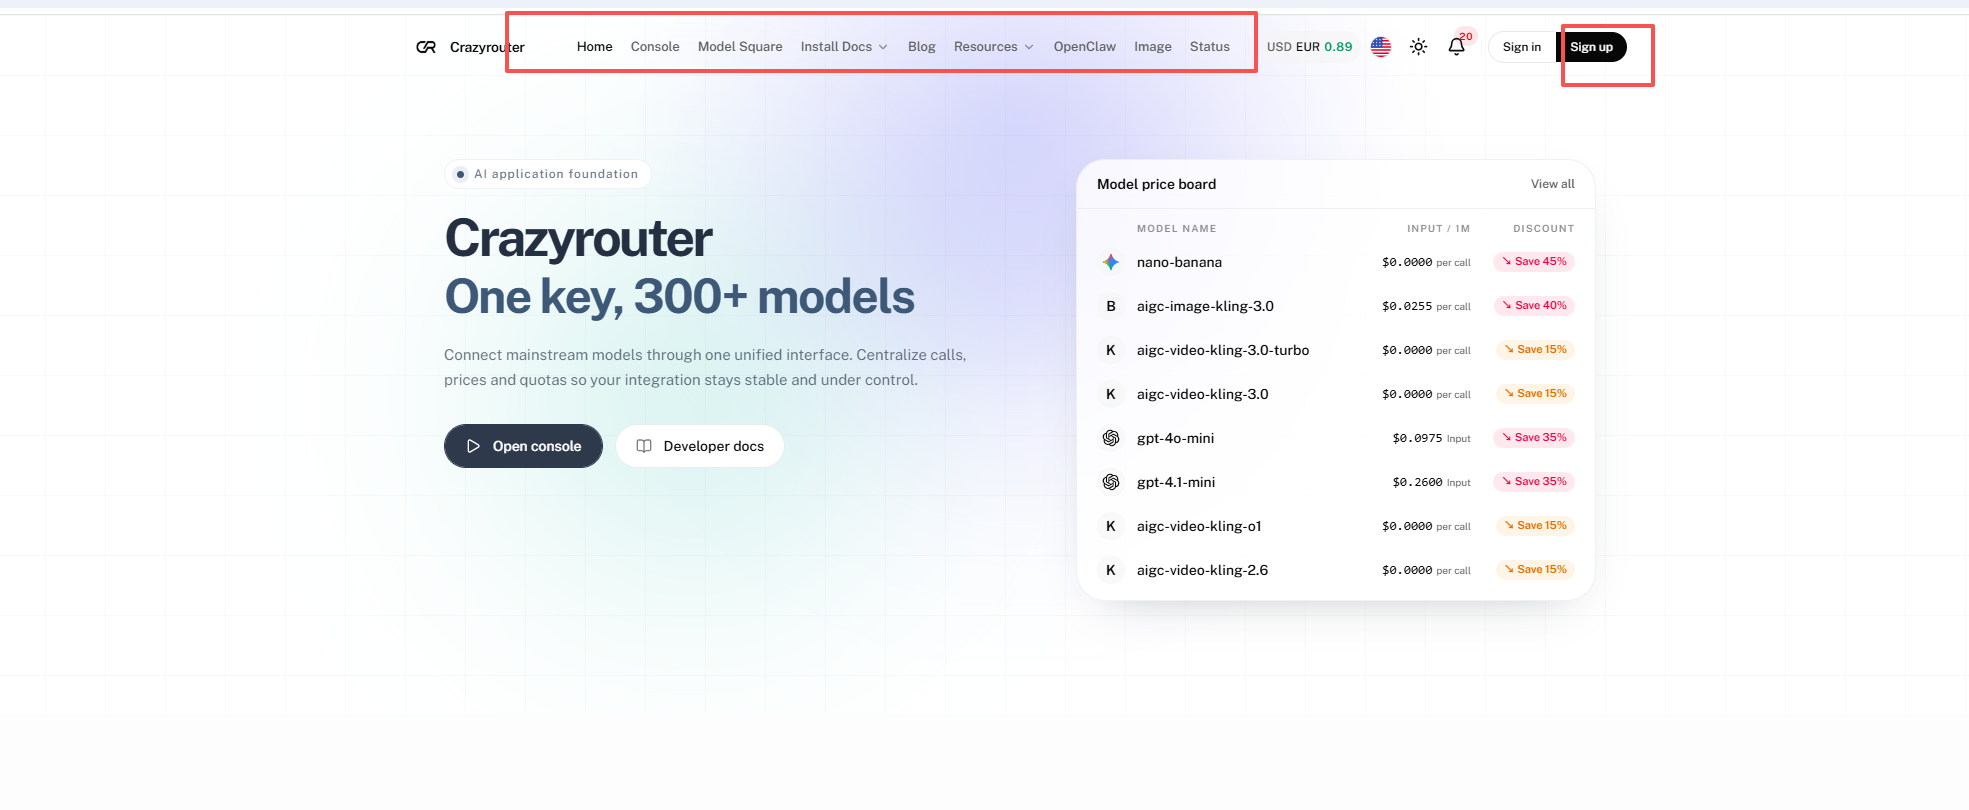
Learn Crazyrouter registration, API keys, wallet checks, browser chat, image generation, and coding-tool setup with eight interface screenshots and practical troubleshooting advice.

Change the card used for Claude Pro, Max, Team, or API billing, with the right steps for web, Apple, Google Play, and Anthropic Console accounts.

A developer-focused Kimi K2 Thinking postmortem about action verification, tool-call boundaries, retries, and practical Python, Node.js, and cURL integration patterns.

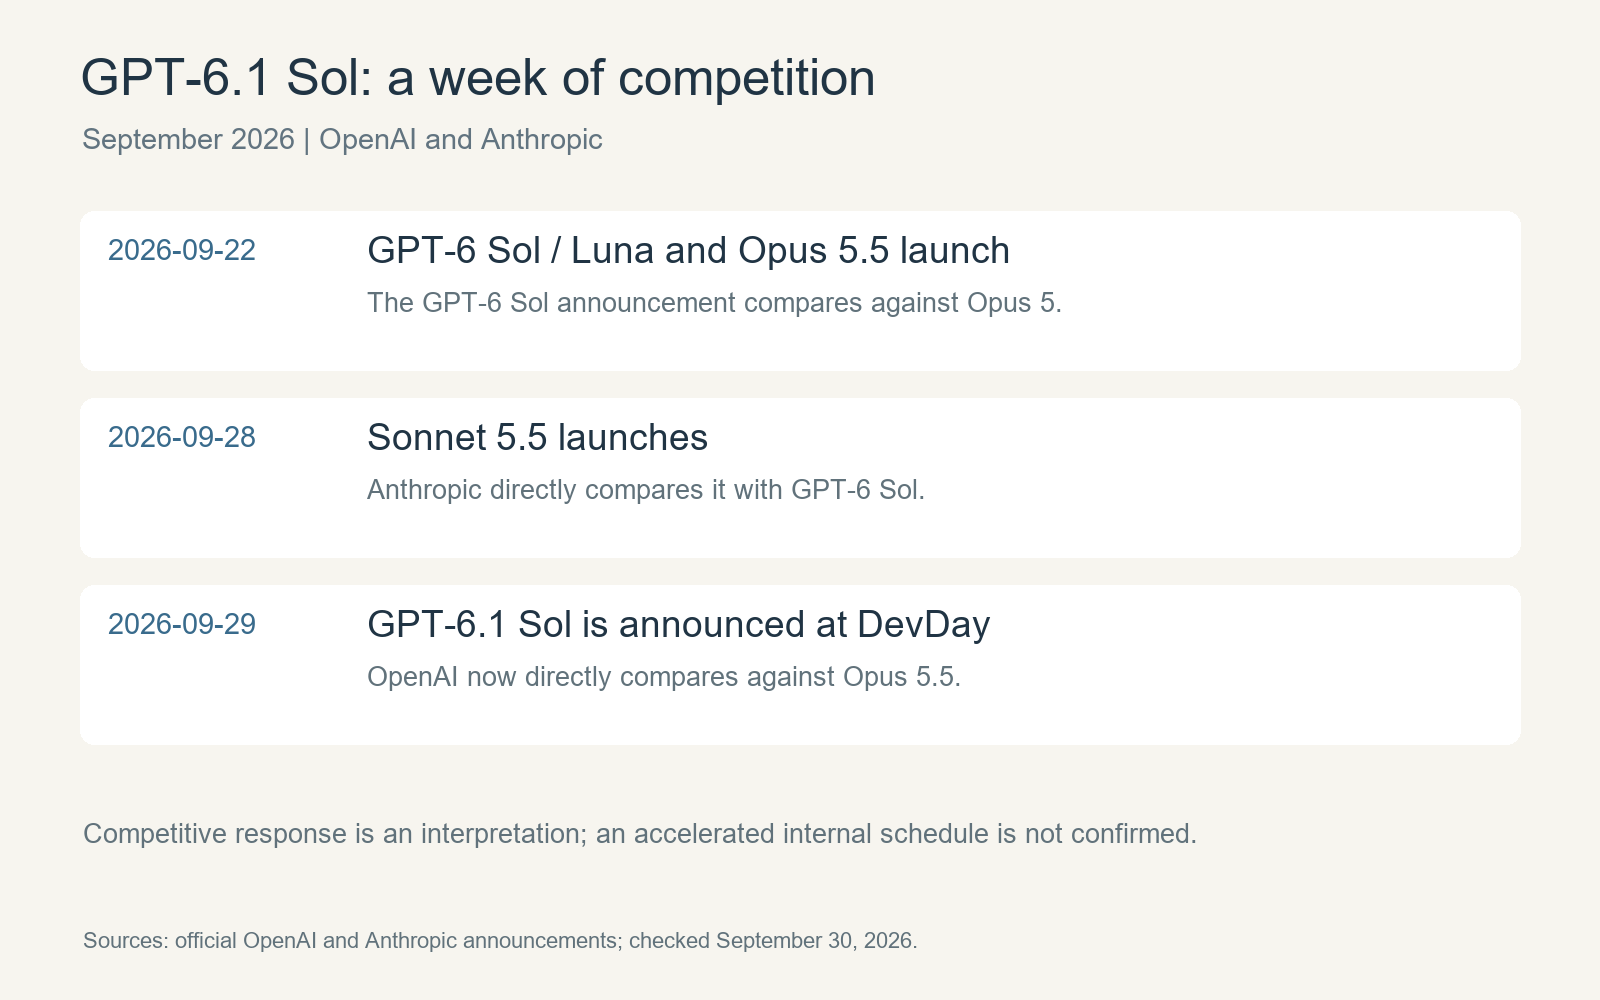
GPT-6.1 Sol arrived just a week after GPT-6 Sol. I examine the competitive pressure from Claude 5.5, OpenAI’s reported gains, and what my API tests reveal about accuracy, timeouts, and readiness for everyday work.

Anthropic has no free tier for the Claude API — the free plan is the claude.ai chat app. Here is what access actually exists in 2026: occasional Console trial credits, cloud provider credits, and prepaid gateways like Crazyrouter at 35% below list, with the limits of each.

Claude API pricing for every current model in one table: Anthropic list price, cached-input price and the Crazyrouter price per 1M tokens, plus monthly cost examples, how billing works, and how to get started.

The open-source versus commercial AI model decision is really a deployment decision. Open-weight models offer control over hosting, tuning, and data boundaries. Commercial models often provi

An AI SaaS can become expensive before it becomes popular if every request uses a large model, long context, and unlimited retries. Budget-conscious architecture starts with unit economics:

A benchmark that tests only accuracy will miss latency, cost, refusal behavior, schema validity, and regression risk. Build a versioned evaluation set from real but sanitized tasks. Score ex

A provider abstraction should hide transport and lifecycle differences, not erase useful capabilities. Define a stable core for messages, tools, usage, errors, and tracing. Keep provider ext

AI observability connects model behavior to business outcomes. Log request IDs, model, latency, token counts, status, safety decisions, and user or tenant budgets while redacting sensitive c

AI APIs fail in recognizable ways: timeouts, rate limits, invalid requests, provider outages, and malformed model output. Production clients should classify errors before retrying. Retry tra

AI API security is broader than hiding an API key. A production integration must protect credentials, control what data leaves your system, constrain model-initiated tools, and prevent one f

Function calling lets a model request a typed operation such as searching a database, creating a ticket, or looking up an order. The model must never receive unrestricted access to your infr

GLM 4.6 is a general-purpose model option for developers evaluating Chinese and multilingual applications, reasoning workflows, code assistance, and tool use. A useful GLM 4.6 API integratio

Qwen2.5-Omni is a multimodal model family designed for workflows that combine text, images, audio, and video understanding. For developers, the important question is not whether a model can

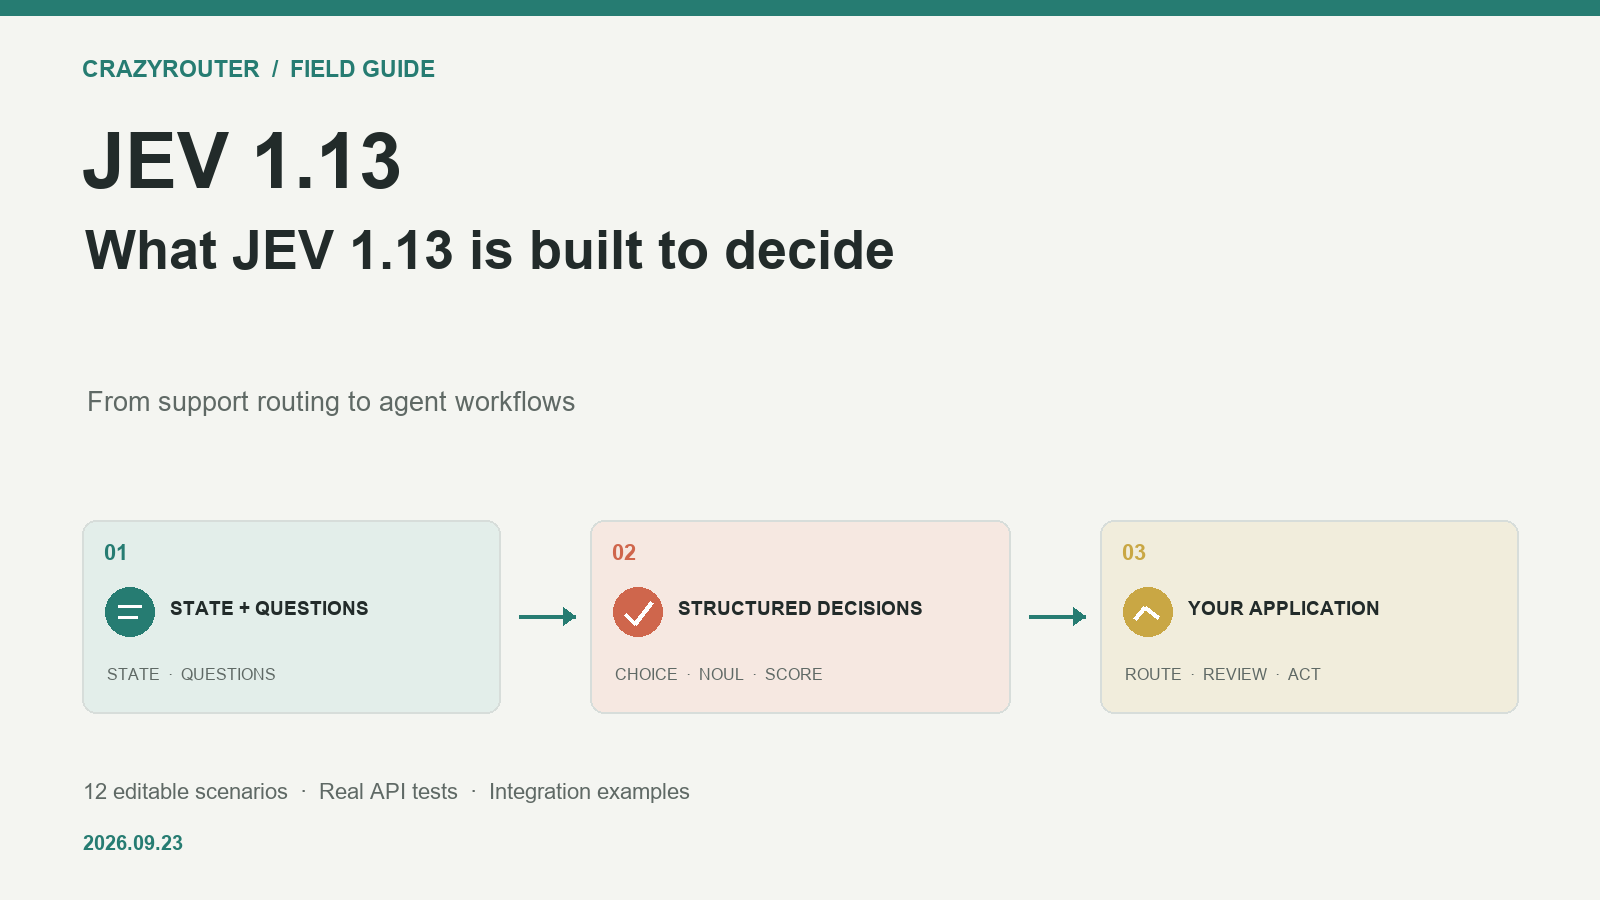
JEV 1.13 excels at turning natural language into choices, probabilities, and scores that programs can use directly. Using real-world calls for Chinese customer-service triage, refund decisions, and RAG filtering, this article explains the three usage patterns—Choice, Noul, and Score—and guides you through 12 editable scenarios in the Crazyrouter JEV Decision Playground, where you can inspect results and copy API integration code.

Learn what Qwen2.5-Omni does, when to use it, how to call multimodal inputs, and how to design cost-aware production integrations.

"Learn how to evaluate Kimi K2 Thinking for reasoning, coding, tool use, and long-context tasks, with OpenAI-compatible examples and production cost guidance."

"A developer guide to Seedance and ByteDance video AI covering use cases, prompting, asynchronous API integration, alternatives, pricing models, and production checks."
"Learn how to integrate Google Veo3-style video generation with cURL and Python, design asynchronous polling, validate outputs, and compare direct versus gateway access."

"Compare AI lip sync tools for creators and developers by input requirements, language support, realism, latency, pricing model, and API integration."

"A practical Codex CLI installation guide covering prerequisites, authentication, project setup, safe permissions, troubleshooting, and API-compatible model routing."
"Learn how to get a Claude API key, configure authentication, send your first request, handle billing, and use a compatible gateway without exposing secrets."
"Compare AI API pricing in 2026 by token economics, context, caching, batch work, and production workflow. Includes code examples and a practical gateway cost model."

"A practical Gemini Advanced review for developers: compare the subscription experience with Gemini API access, long-context workflows, coding, multimodal tasks, and cost control."

"A developer-focused Claude Code pricing guide covering subscriptions, API billing, model selection, usage controls, and a practical lower-friction workflow for teams."

Learn how prompt caching, semantic caching, context pruning, and retrieval reduce AI API latency and spend without sacrificing answer quality.

A benchmark that tests only accuracy will miss latency, cost, refusal behavior, schema validity, and regression risk. Build a versioned evaluation set from

A provider abstraction should hide transport and lifecycle differences, not erase useful capabilities. Define a stable core for messages, tools, usage, err

Record request IDs, usage, latency and validated outcomes without logging prompts. A tested Python embedding example explains retries and cost reconciliation.

Build bounded AI API retries in Python with Retry-After, jitter, attempt limits, and an overall deadline. Includes tested failure cases and safe replay rules.

Compare open-weight and commercial AI models across cost, quality, privacy, operations, licensing, and API integration.

A practical guide to launching an AI SaaS with usage quotas, model routing, caching, observability, and predictable unit economics.

A developer checklist for securing AI APIs against leaked keys, prompt injection, sensitive-data exposure, unsafe tools, and runaway spend.

Learn how to design portable function calling across OpenAI-compatible, Anthropic, Gemini, and open-model APIs with schemas, validation, retries, and routing.

A practical Qwen2.5-Omni guide for real-time voice-and-vision apps with barge-in, turn detection, latency budgets, and API cost controls.

Build reliable Kimi K2 Thinking applications with explicit reasoning budgets, tool-call validation, evaluation sets, and cost controls.

A developer guide to Seedance video AI integration with asynchronous queues, cost controls, prompt versioning, and model fallbacks.

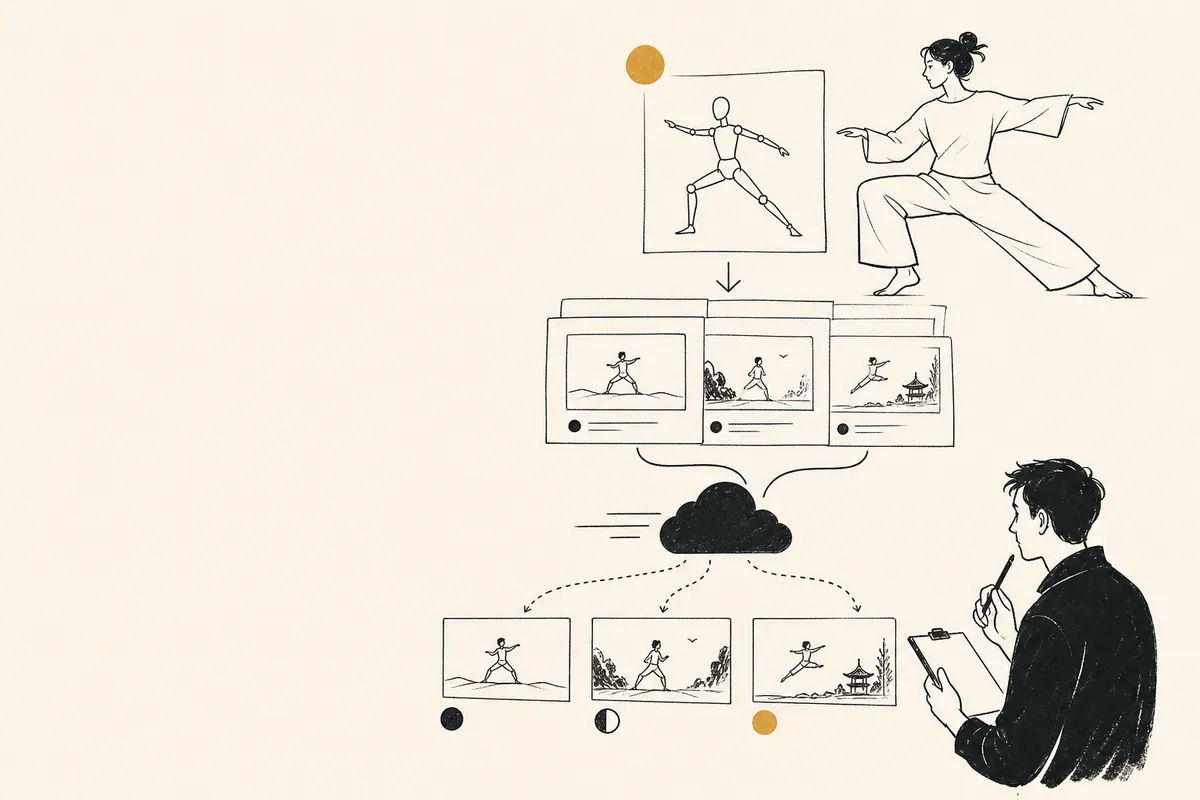
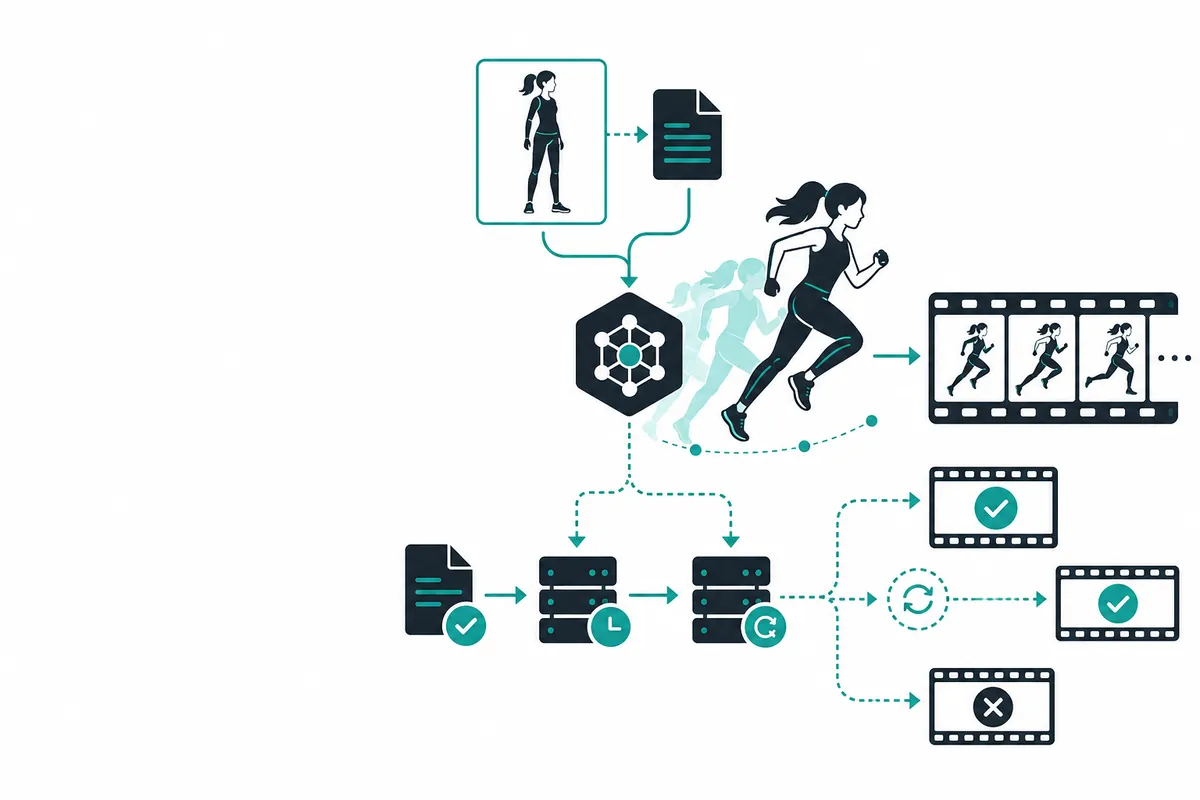
Learn a production-friendly WAN 2.2 Animate workflow for reference poses, shot manifests, asynchronous jobs, and visual QA.

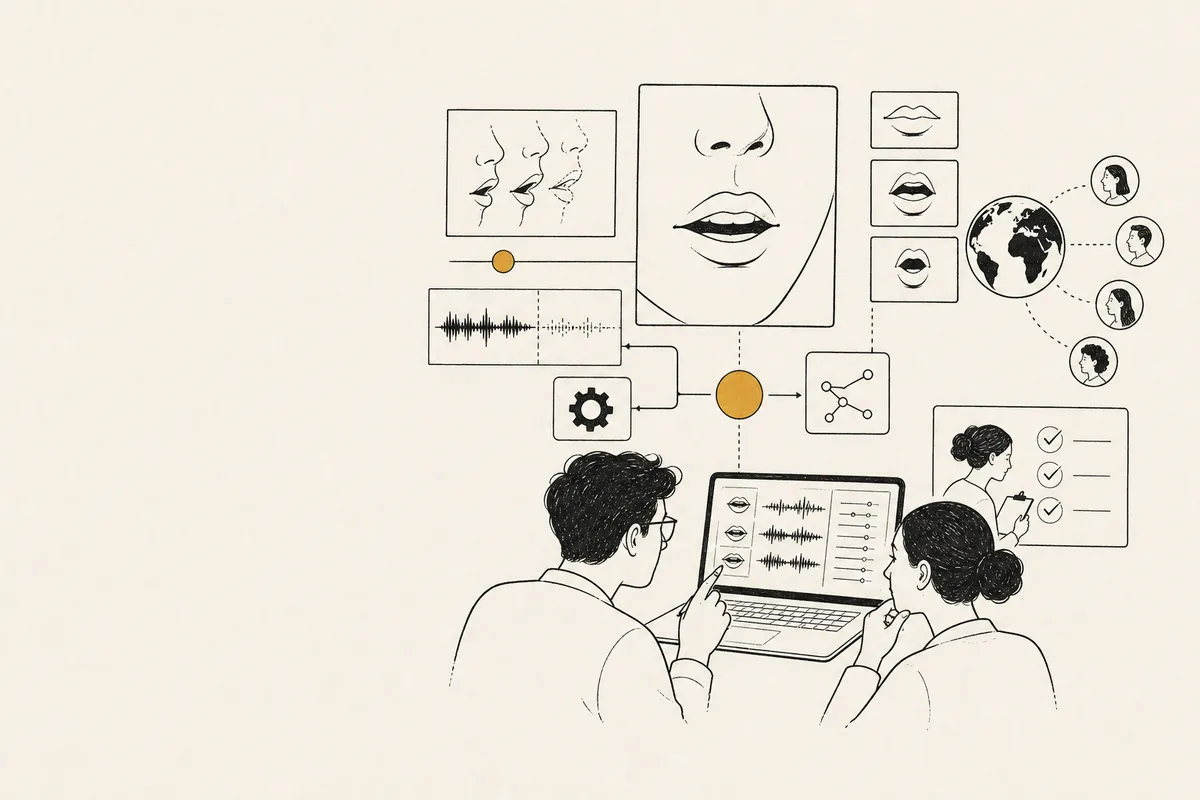
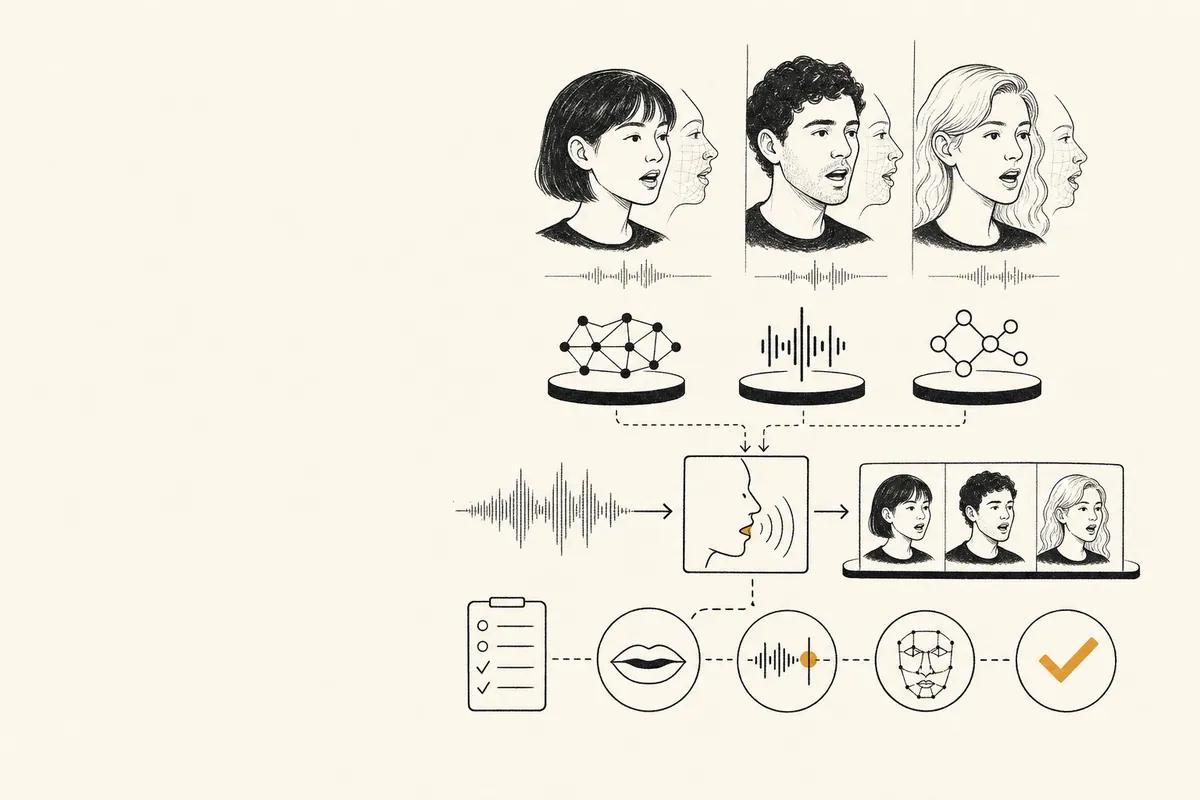
Compare AI lip sync tools for developers using phoneme drift, frame alignment, multilingual dubbing, API control, and production QA.

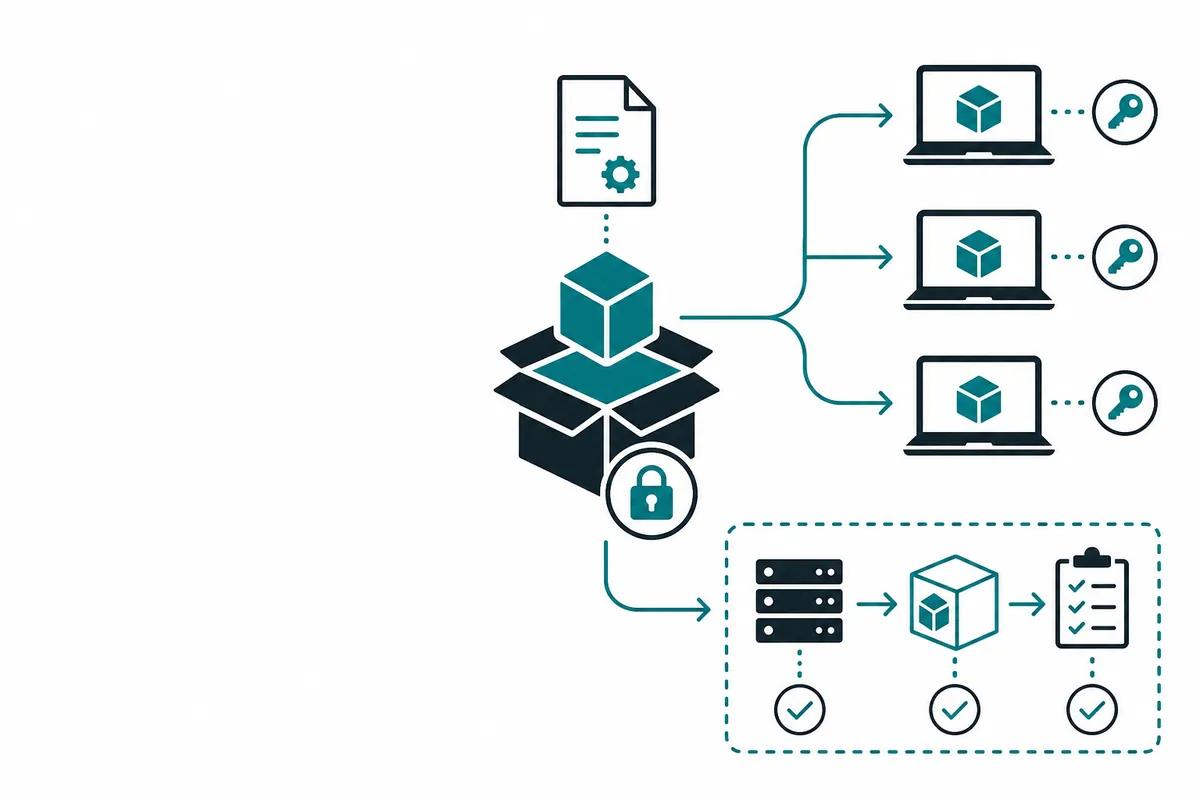
Install Codex CLI reproducibly across developer machines and CI with version pinning, isolated credentials, and container checks.

A secure setup guide for obtaining and using a Claude API key across local development, devcontainers, and CI without committing secrets.

Compare AI API pricing by successful task, latency, caching, retries, and routing policy instead of token price alone.

A developer-focused Gemini Advanced review covering long-context analysis, RAG prototyping, subscription versus API economics, and production handoff.

A practical developer guide to estimating Claude Code costs by repository, workflow, seat, and CI job, with budget controls and API routing patterns.

29 graded items, real API calls. claude-fable-5-1 scored 29/29, gpt-6-astra 16/29. astra emits 0.38-0.77x the output characters, but much of that gap is incompleteness rather than concision — on a three-way tie it named one answer in 5 of 6 runs, and 2 of those named a rule that is factually wrong. On a planted false premise it went along with the premise 5 times out of 6. Includes the three preconditions for valid cross-family comparison.

Compare open source and commercial AI models across cost, privacy, quality, latency, operations, licensing, and API integration.

Learn how to launch an AI SaaS economically using model routing, usage limits, caching, asynchronous jobs, and a unified AI API.

Implement robust error handling for AI APIs with timeout budgets, exponential backoff, idempotency, validation, streaming recovery, and provider fallbacks.

Build reliable multi-model AI systems with task routing, fallbacks, cost controls, evaluation, and a unified API layer.

Design portable function calling across OpenAI-compatible, Claude, Gemini, and open-model APIs with schemas, validation, retries, and fallbacks.

Protect AI API keys, tenant data, prompts, logs, and budgets with practical controls for production applications.

Install and evaluate Gemini CLI, compare it with Claude Code and Codex CLI, and connect reliable Gemini API workflows to your developer tools.

A developer-focused Pika 2.2 review covering video generation use cases, alternatives, API integration patterns, pricing questions, and production tips.

A practical GLM-4.6 API guide for developers covering capabilities, alternatives, OpenAI-compatible requests, pricing decisions, and production safeguards.

Learn what Qwen2.5-Omni is, how it compares with GPT-4o and Gemini, how to call a multimodal model, and how to control API cost in production.

A developer guide to Qwen2.5-Omni for voice, vision, interruption handling, streaming, and production cost controls.

Use Kimi K2 Thinking for auditable reasoning tasks with bounded tool calls, evaluation sets, and cost-aware routing.

Build a reliable Google Veo3 API integration with async jobs, audio-aware prompts, webhooks, retries, and budget controls.

A practical WAN 2.2 Animate tutorial for controlled character motion, reference images, asynchronous jobs, and production retries.

Compare AI lip sync tools for developers building dubbing, avatar, and localization pipelines with measurable QA gates.

Learn how to get a Claude API key, configure it safely, test the first request, and avoid leaking credentials in Git or CI logs.

Compare AI API pricing by tokens, cached context, retries, latency, and routing instead of relying on headline input rates.

A developer-focused Gemini Advanced review covering research, coding, context, subscription value, API economics, and practical alternatives.

A practical Claude Code pricing guide for solo developers and teams, covering subscriptions, API usage, CI budgets, and routing controls.

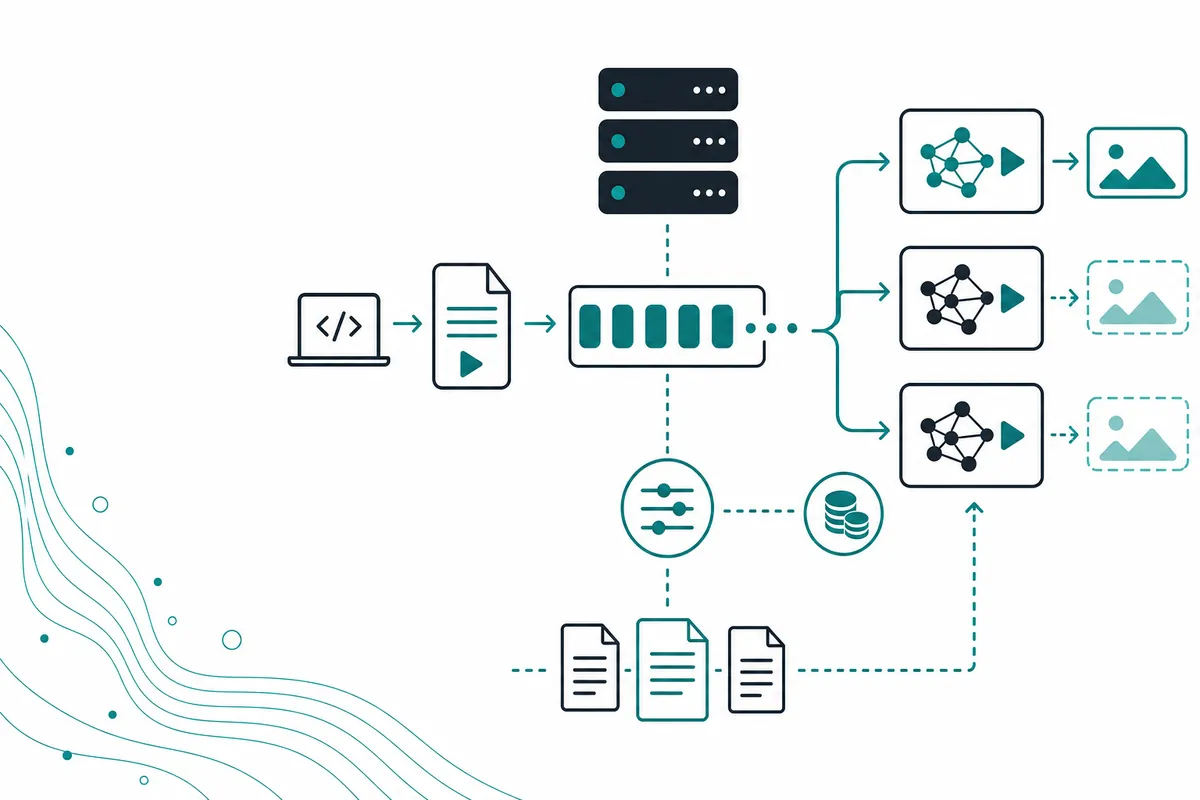
Design reliable asynchronous AI jobs for image, video, audio, and long-running agent tasks using queues, polling, webhooks, and idempotency.

Build a practical test and evaluation system for AI APIs with fixtures, schema checks, regression sets, latency budgets, and human review.

Reduce AI API spending with prompt budgeting, response caching, model cascades, batching, and usage-based cost attribution.

Implement production AI streaming with Server-Sent Events, cancellation, backpressure, reconnects, and usage tracking.

Compare open source and commercial AI models by cost, quality, deployment, privacy, latency, and maintenance burden.

A practical blueprint for launching an AI SaaS with usage limits, model routing, caching, tenant isolation, and predictable margins.

Design resilient AI API clients with timeout budgets, error classification, exponential backoff, fallback models, and observable request IDs.

Build portable tool calling across OpenAI-compatible, Anthropic, and Gemini-style APIs with schemas, adapters, validation, and retries.

An AI API is an external boundary, even when it sits behind a friendly SDK. Your application sends prompts, files, tool definitions, and sometimes personal data to a model provider. A leaked key can c...

"A developer-focused Kimi K2 Thinking guide covering reasoning prompts, tool calling, evaluation, latency, and cost-aware routing."

"Understand Seedance and ByteDance video AI, compare it with Veo3 and Kling, and design an API pipeline for controlled production."

"Learn how to integrate Google Veo3 API workflows with async jobs, webhooks, audio-aware prompts, retries, and a pricing model."

"Build a reliable WAN 2.2 Animate workflow with image inputs, motion prompts, asynchronous jobs, retries, and cost controls."

"Compare AI lip sync tools for developers by API design, timing quality, multilingual support, and automated production QA."

"Learn how to get a Claude API key, configure it safely, rotate credentials, and use an OpenAI-compatible router for team deployments."

"Compare AI API pricing in 2026 using effective cost per task, including cache hits, retries, fallback models, and Crazyrouter routing."

"Review Gemini Advanced for coding, research, and API workflows in 2026. Compare subscription value with usage-based API access and multi-model routing."