Opus 4.8 vs Opus 4.7 for Agents: JSON, Tool Use, and Structured Output
Our real API test found Opus 4.7 cleaner than Opus 4.8 for strict JSON-style output, while Opus 4.8 remained strong for reasoning and explanation.
Model updates, integration guides, pricing breakdowns, and tool workflows for developers and teams.

Our real API test found Opus 4.7 cleaner than Opus 4.8 for strict JSON-style output, while Opus 4.8 remained strong for reasoning and explanation.

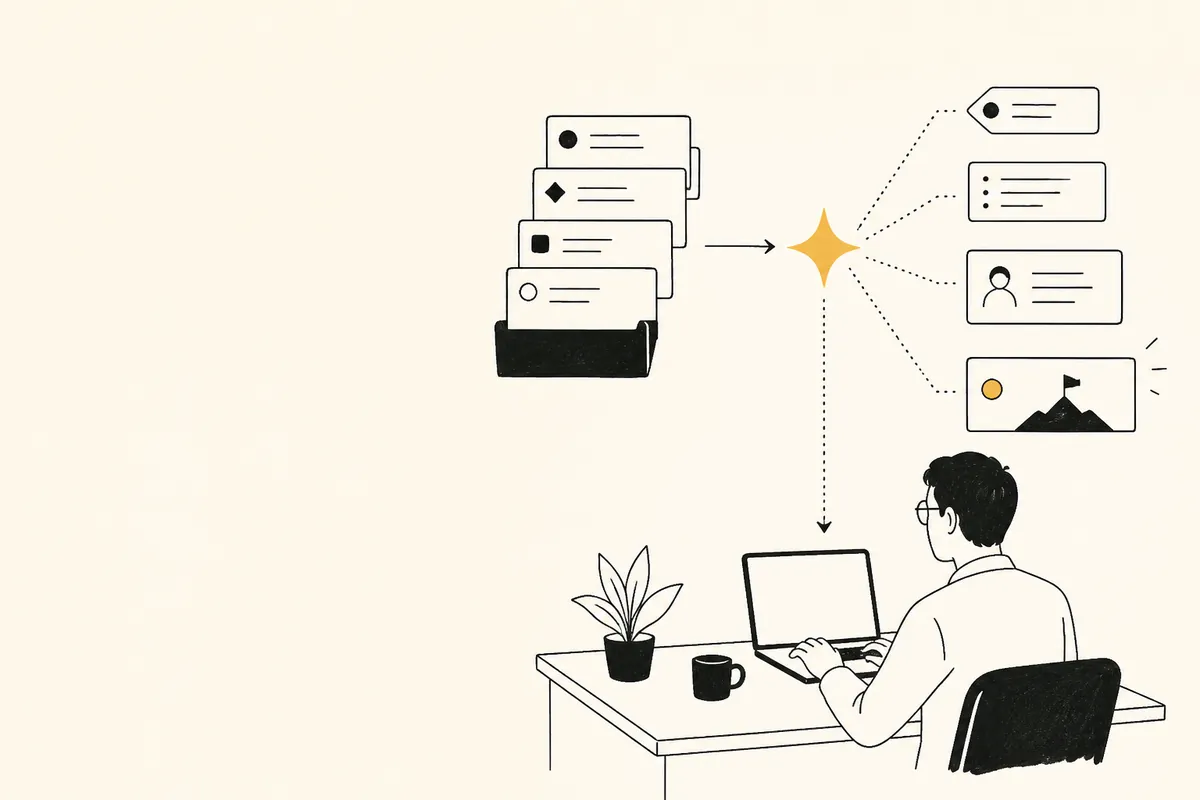
A developer guide to using Gemini 2.5 Flash-Lite as a routing and evaluation layer in RAG and agent systems, with practical metrics beyond cost per token.

How developers can use Gemini 2.5 Flash-Lite to classify support tickets, extract key fields, suggest next actions, and escalate risky cases without turning support into an unreliable chatbot.

A practical guide to where Gemini 2.5 Flash-Lite fits: high-volume classification, extraction, routing, enrichment, and other automation jobs where latency and unit economics matter more than deep reasoning.

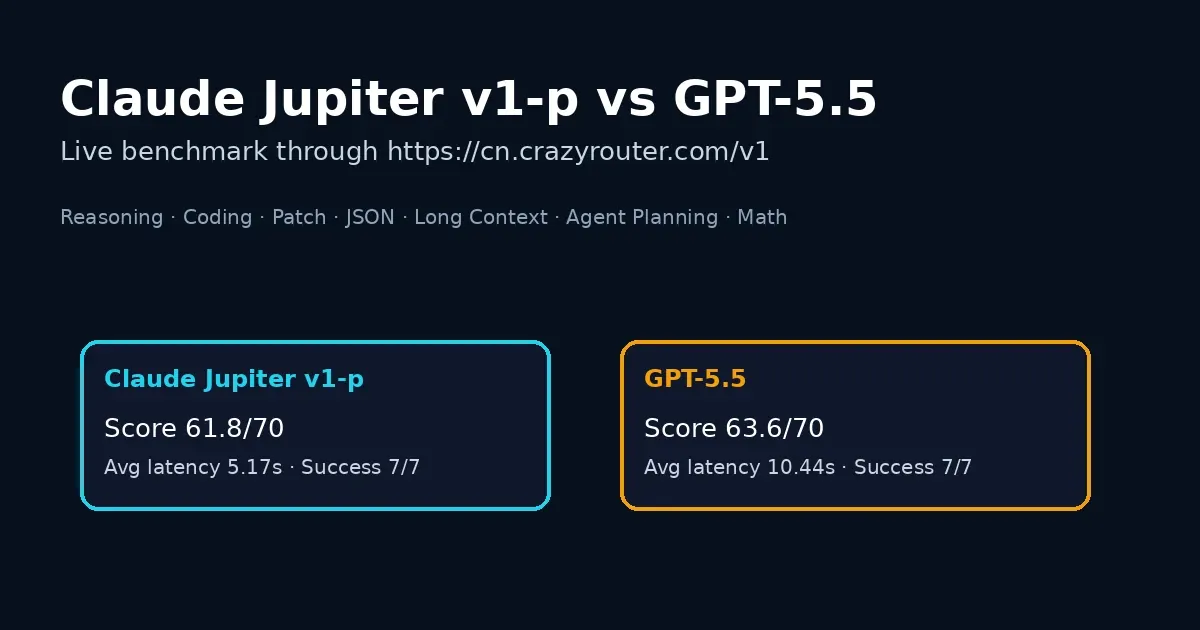
We tested claude-jupiter-v1-p and gpt-5.5 through https://cn.crazyrouter.com/v1 across reasoning, coding, patching, JSON, long-context recall, agent planning, and math tasks. GPT-5.5 scored slightly higher, while Jupiter was much faster but required a payload compatibility fix.

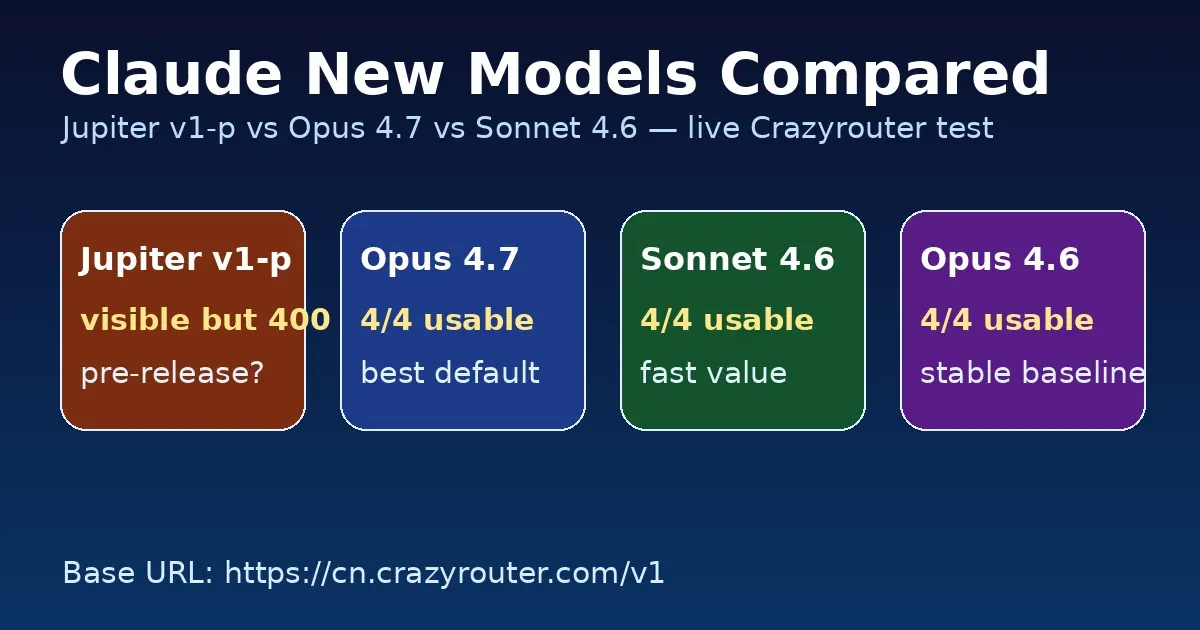
A live Crazyrouter API test comparing claude-jupiter-v1-p, claude-opus-4-7, claude-sonnet-4-6, and claude-opus-4-6 for coding and structured output workflows.

A live Crazyrouter API test comparing claude-jupiter-v1-p, claude-opus-4-7, claude-sonnet-4-6, and claude-opus-4-6 for coding and structured output workflows.

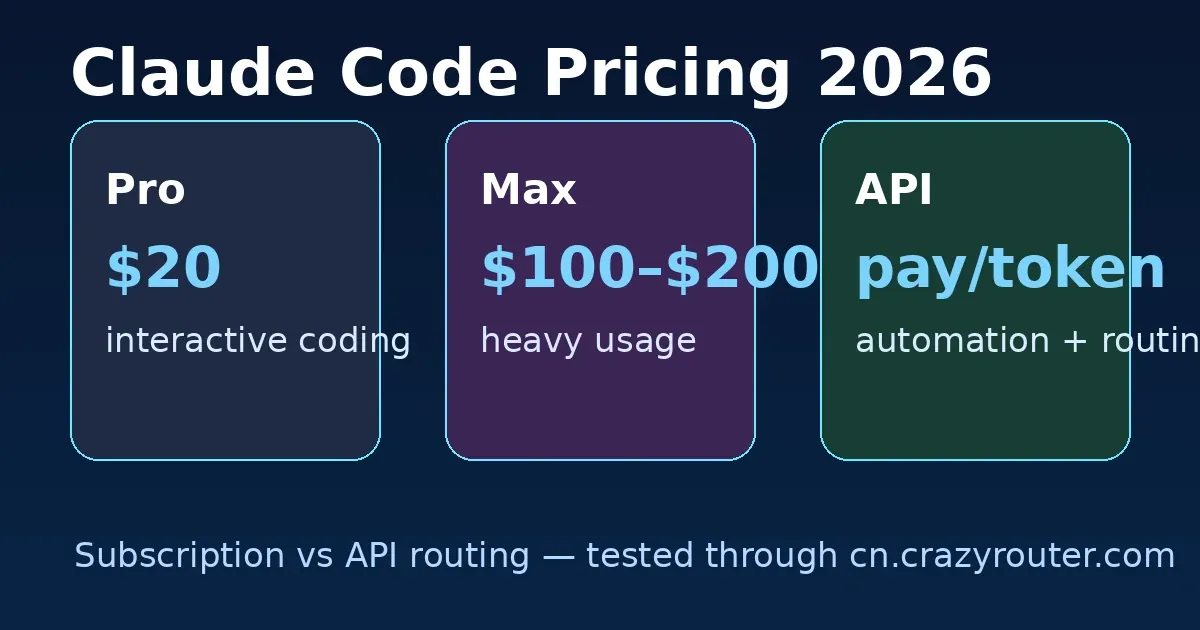
A practical Claude Code pricing guide based on live coding workflow tests through https://cn.crazyrouter.com/v1, comparing subscription plans with API routing and cost per successful task.