Crazyrouter Blog

Practical notes on AI models, API costs, and production workflows.

Model updates, integration guides, pricing breakdowns, and tool workflows for developers and teams.

Explore by topic

View all topics
GPT-7 Outlook: What Do OpenAI’s 722 Mathematics Manuscripts Actually Tell Us?
October 11, 2026128 viewsEnglishNews

GPT-7 Outlook: What Do OpenAI’s 722 Mathematics Manuscripts Actually Tell Us?

Explore the GPT-7 speculation around 722 mathematics manuscripts: what the video claims, what Lean can verify, and what remains unknown about OpenAI’s unnamed model.
AWS Bedrock Anthropic Claude Pricing per 1M Tokens
October 10, 2026208 viewsEnglishGuide

AWS Bedrock Anthropic Claude Pricing per 1M Tokens

Read Claude pricing on Bedrock by model and token type, calculate a workload estimate, and avoid confusing standard rates with caching or provisioned capacity.

Nano Banana 2.1 vs Nano Banana 2: Three API Tests and Price
October 10, 2026153 viewsEnglishComparison

Nano Banana 2.1 vs Nano Banana 2: Three API Tests and Price

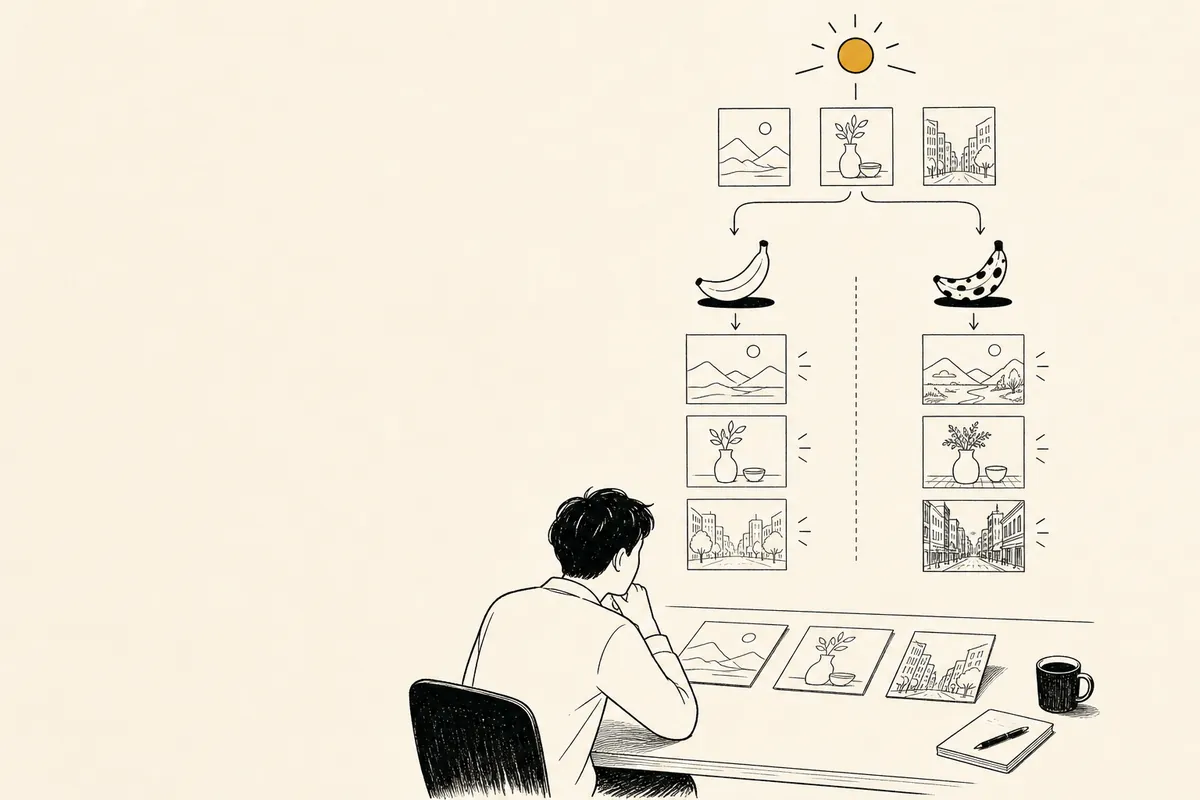
We ran the same three prompts through both image routes, inspected all six files, and compared latency, prompt compliance, billing, and integration behavior.

What Is Nano Banana 2.1? Image API, Price, and a Real Request
October 9, 2026228 viewsEnglishGuide

What Is Nano Banana 2.1? Image API, Price, and a Real Request

Understand the Nano Banana 2.1 image route, its published billing unit, and the exact request that returned an image in our October test.

Crazyrouter User Guide: From Registration and API Keys to Chat and Image Generation
October 9, 2026159 viewsEnglishTutorial

Crazyrouter User Guide: From Registration and API Keys to Chat and Image Generation

Learn Crazyrouter registration, API keys, wallet checks, browser chat, image generation, and coding-tool setup with eight interface screenshots and practical troubleshooting advice.

Claude Haiku 5.5 vs DeepSeek V4.1 Flash: Everyday Benchmark
October 9, 2026219 viewsEnglishComparison

Claude Haiku 5.5 vs DeepSeek V4.1 Flash: Everyday Benchmark

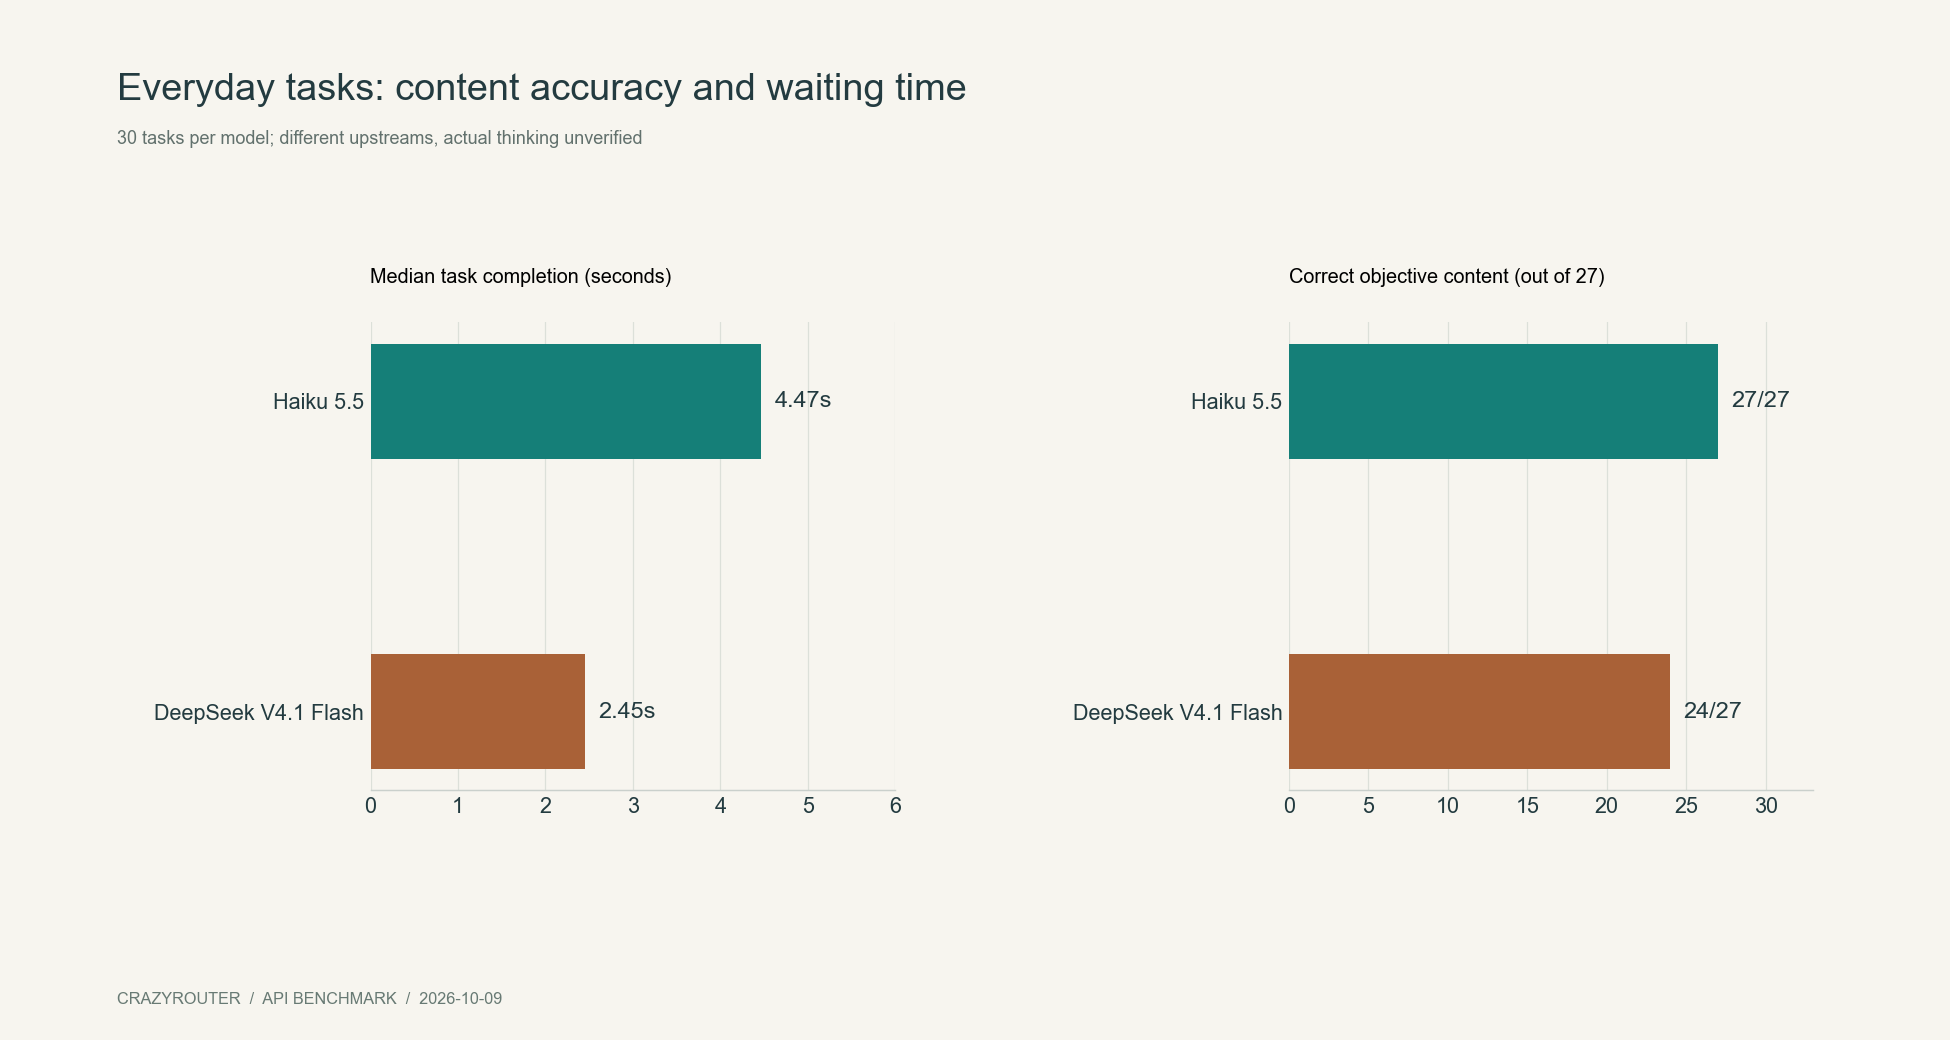
Ten Chinese tasks, three runs each: content scores of 27/27 vs 24/27 and median completion of 4.47s vs 2.45s. JSON, actual charges, errors, and the limits of route, cache, and thinking controls.

Claude Haiku 5.5 vs Sonnet 4.6: An Everyday Benchmark
October 8, 2026173 viewsEnglishComparison

Claude Haiku 5.5 vs Sonnet 4.6: An Everyday Benchmark

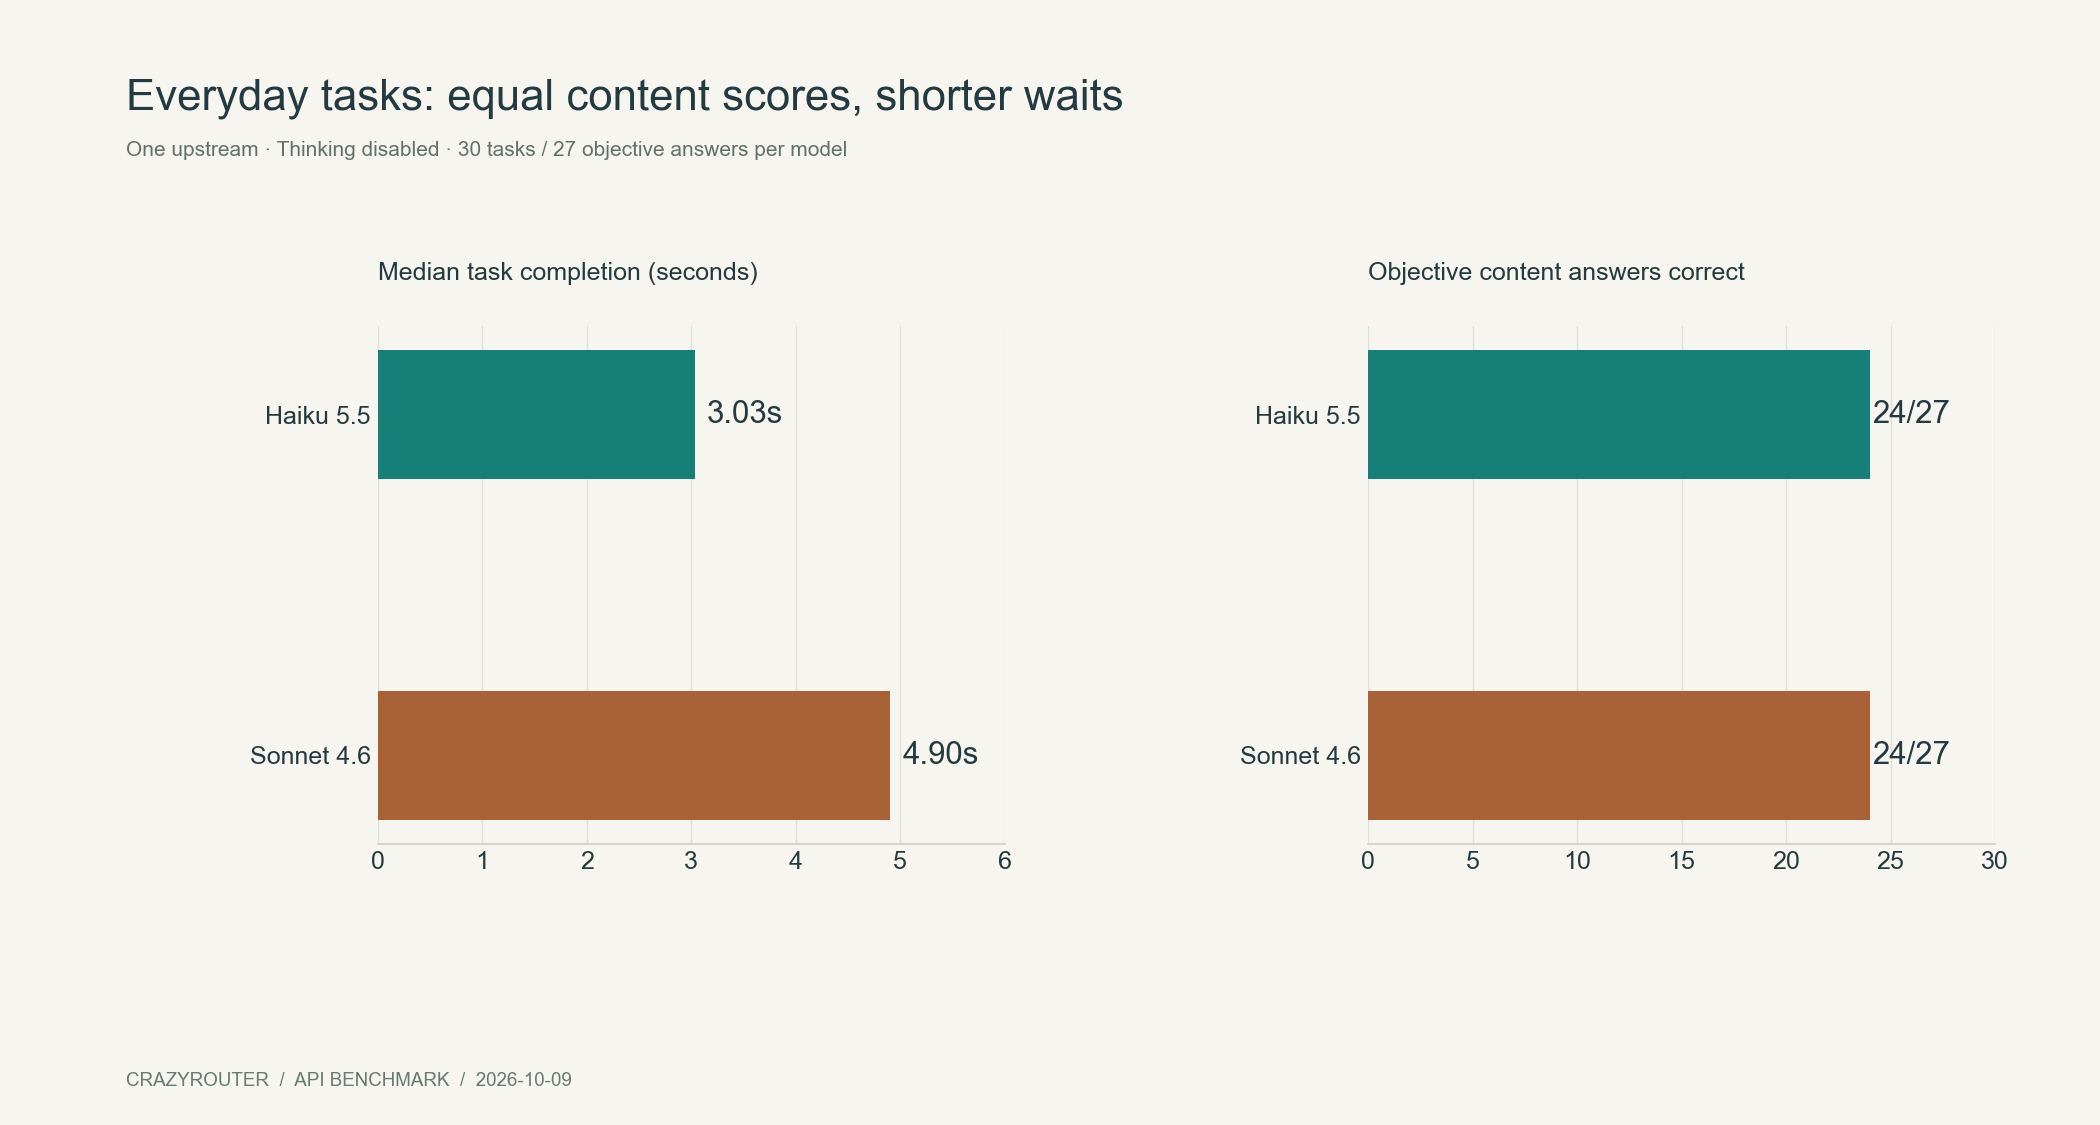
Ten tasks, three rounds each, on one upstream route. Both models scored 24/27 for objective content; median completion was 3.03s vs 4.90s. We examine JSON failures, a thinking retest, and rewriting mistakes.

How to Change Your Claude Payment Method in 2026
October 7, 2026268 viewsEnglishTutorial

How to Change Your Claude Payment Method in 2026

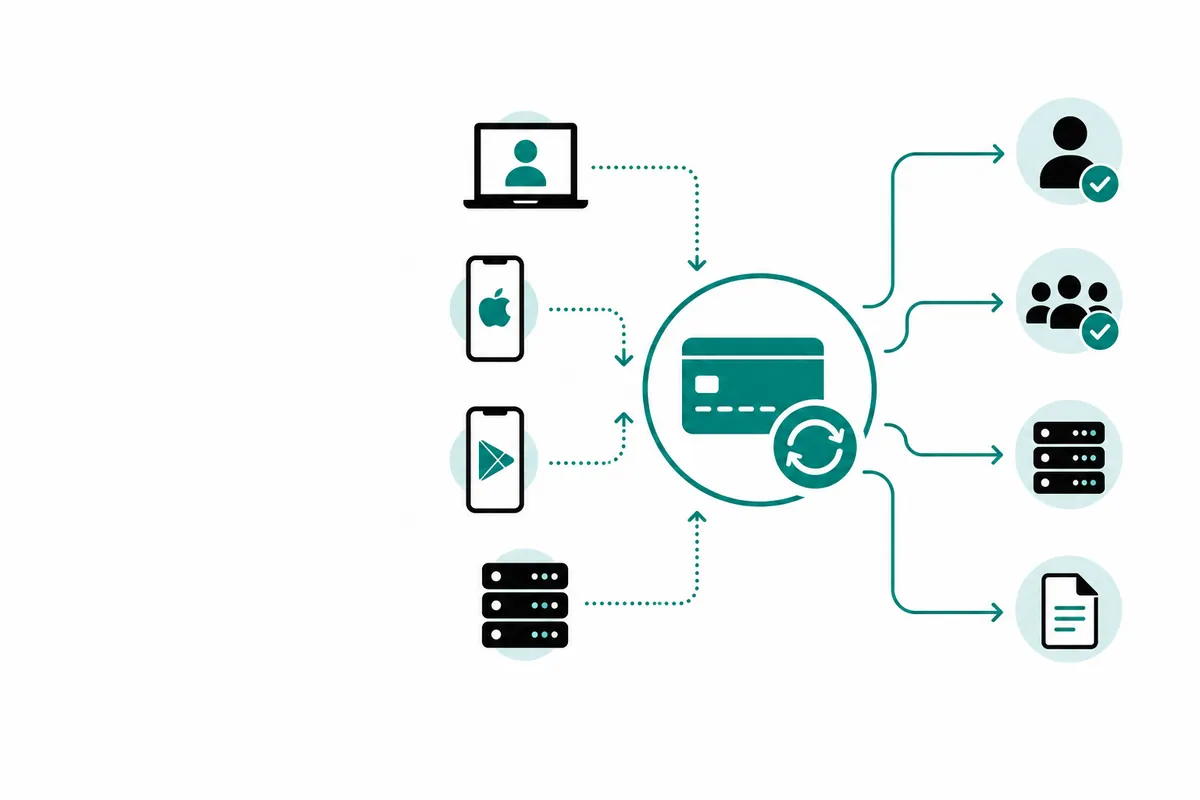
Change the card used for Claude Pro, Max, Team, or API billing, with the right steps for web, Apple, Google Play, and Anthropic Console accounts.