简体中文
 繁體中文
 English
 Français
 Русский
 日本語
 Tiếng Việt
 한국어
 Deutsch
 Español
 Italiano
 Português
 العربية
 ไทย
 Bahasa Indonesia
 Bahasa Melayu
 Türkçe
 Polski
 Nederlands
 Dansk
 Norsk
 Қазақша
GLM-5.3 vs GLM-5.2: A Hard Benchmark with Real API Calls
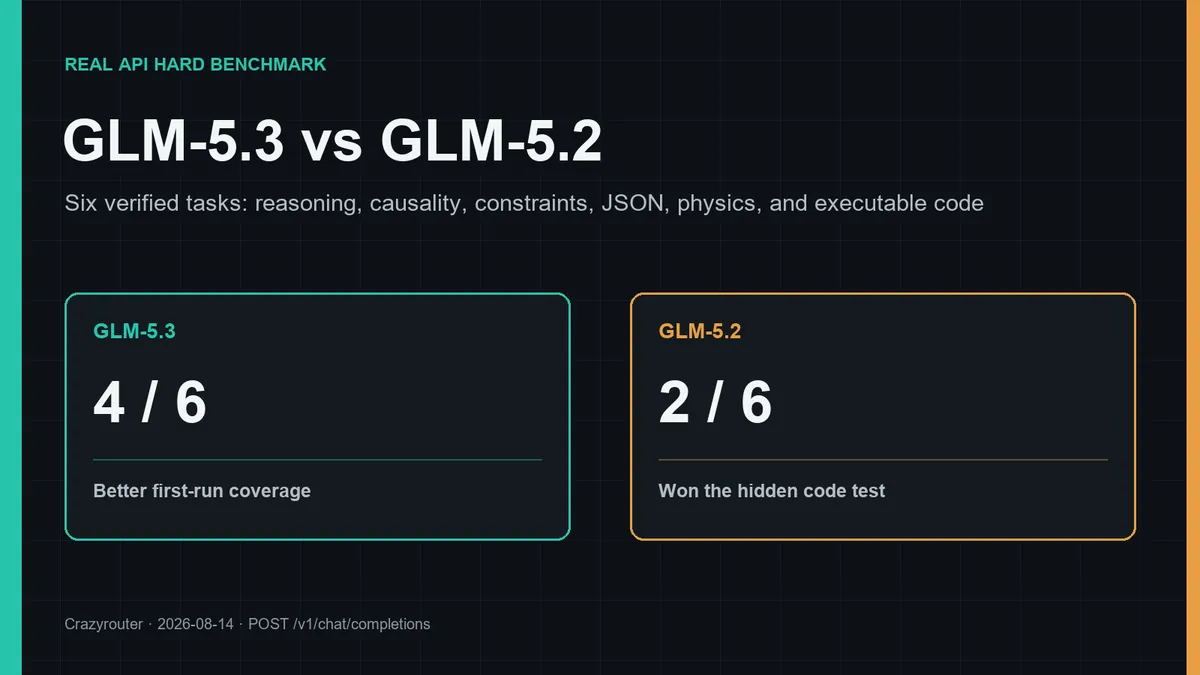
Six hard, verifiable API tasks comparing GLM-5.3 and GLM-5.2. GLM-5.3 led first-delivery coverage 4/6 to 2/6, while GLM-5.2 won the hidden code test.
GLM-5.3 vs GLM-5.2: A Hard Benchmark with Real API Calls#
The first benchmark showed that GLM-5.3 was more likely to deliver visible answers within a fixed output budget. This follow-up raised the difficulty across six objectively verifiable tasks: extreme mathematics, causal calibration, constraint reasoning, nested JSON, multi-stage physics, and executable optimization code.
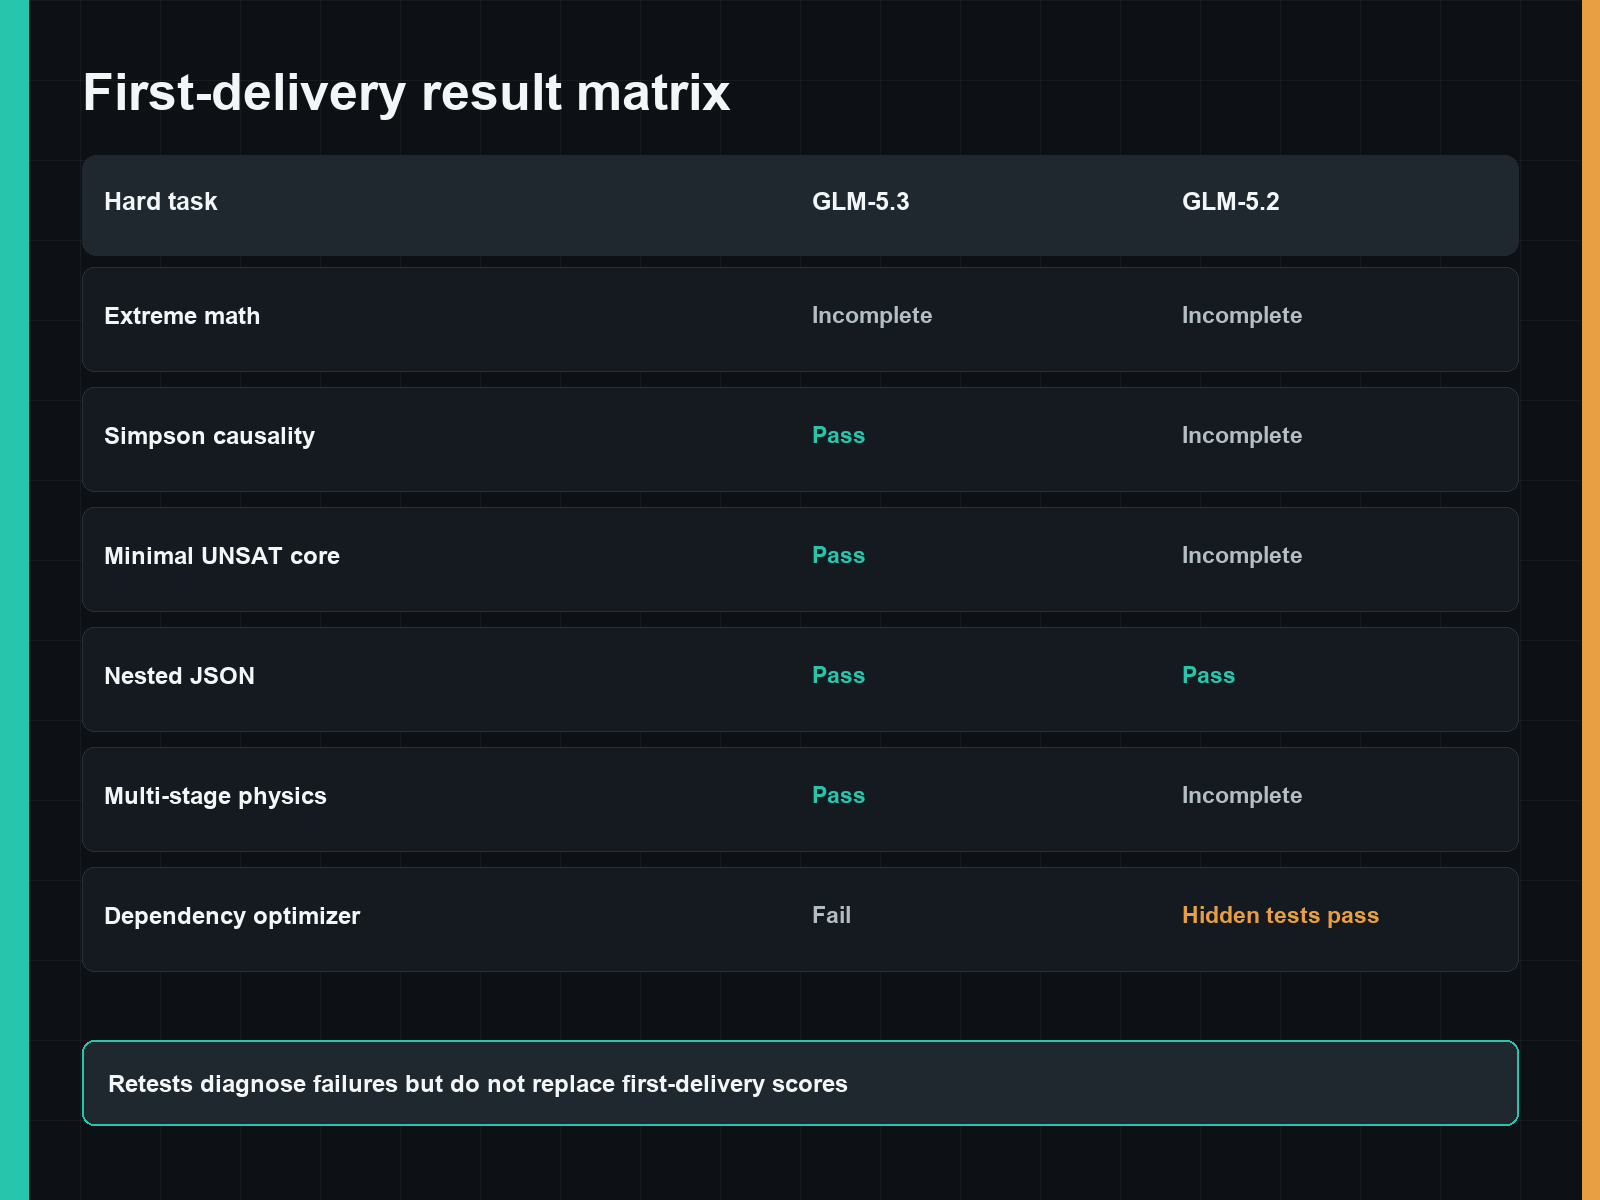
The first-delivery score was 4/6 for GLM-5.3 and 2/6 for GLM-5.2. That headline does not tell the whole story: GLM-5.2 produced the only dependency optimizer that passed the hidden test suite, while both models failed the extreme math task.
Test setup#
| Field | Value |
|---|---|
| Base URL | https://cn.crazyrouter.com |
| Endpoint | POST /v1/chat/completions |
| Models | glm-5.3, glm-5.2 |
| Temperature | 0.2 |
| Tools and web access | Disabled |
| Scoring | First delivery only; larger-budget retries were diagnostic |
Before the run, GET https://cn.crazyrouter.com/v1/models listed both exact model IDs. All 12 first-run responses returned the requested model identity.
Results#
| Task | Budget | GLM-5.3 | GLM-5.2 |
|---|---|---|---|
| Unequal-probability coupon collector | 9,000 | Length, empty body | Length, empty body |
| Simpson's paradox and causal limits | 6,000 | Pass | Length, empty body |
| Minimal unsatisfiable core | 5,000 | Pass, strict JSON | Length, empty body |
| Nested regional incident JSON | 4,000 | Pass | Pass |
| Pulley, slack rope, friction, spring | 14,000 | Pass | Length, empty body |
| Dependency-constrained optimizer | 16,000 | Length, empty body | Hidden tests pass |
GLM-5.3 completed four first-run tasks in 334.1 seconds total. GLM-5.2 completed two in 665.0 seconds. Latency was retained as operational evidence but did not change correctness scores.
The extreme math task defeated both models#
The task used four coupon probabilities: 1/2, 1/4, 1/8, 1/8. It required two exact inclusion-exclusion results:
E[T] = 1339/105 ≈ 12.752380952
P(T<=8) = 46179/131072 ≈ 0.352317810
Both models consumed the full 9,000-token reasoning budget and returned no visible answer. A 20,000-token retry still produced an empty body for GLM-5.3; GLM-5.2 exceeded the runner's 420-second read timeout.
This is a useful production warning: raising max_tokens does not guarantee a deliverable answer. A gateway should inspect finish reason, visible content, and timeout state together.
Where GLM-5.3 was stronger#
On the Simpson task, GLM-5.3 correctly recovered the reversal:
Small stones: A 81/87 > B 234/270
Large stones: A 192/263 > B 55/80
Crude total: A 273/350 < B 289/350
50/50 standardized rates: A=0.8305, B=0.7771
It also separated standardization from causal identification, noting the need for randomization or adequate adjustment, positivity, no unmeasured confounding, and uncertainty estimates.
The minimal-UNSAT task required exactly one JSON object. GLM-5.3 returned [1,2,3] and correctly proved that the constraints force C and D into the same position. The response parsed without cleanup.
The physics task required switching system boundaries after the hanging mass hit the ground and the rope went slack. GLM-5.3 matched all four reference values:
a ≈ 0.847 m/s²
v1 ≈ 1.59 m/s
v2 ≈ 1.18 m/s
x ≈ 0.0835 m
Where GLM-5.2 won#
The code task asked for optimize_release_plan(items, capacity_by_day, dependencies) with transitive dependencies, per-day capacities, value maximization, risk and lexical tie-breaks, invalid references, and cycle detection.
GLM-5.2 returned a complete Python file at the 16k budget and passed the external hidden test suite without edits. GLM-5.3 returned no body at 16k. At 24k it finally produced code, but selected a plan worth 24 instead of the correct optimum worth 29, so the retry still failed.
This is why code generation must be executed. Version numbers, code length, and a polished explanation are not substitutes for tests.
OpenAI-compatible request#
import os
import requests

r = requests.post(
    "https://cn.crazyrouter.com/v1/chat/completions",
    headers={"Authorization": f"Bearer {os.environ['CRAZYROUTER_API_KEY']}"},
    json={
        "model": "glm-5.3",
        "messages": [{"role": "user", "content": "Your acceptance task"}],
        "temperature": 0.2,
        "max_tokens": 6000,
    },
    timeout=600,
)

choice = r.json()["choices"][0]
assert choice["finish_reason"] == "stop"
assert choice["message"]["content"].strip()
Production guidance#
- Prefer GLM-5.3 for causal analysis, constraint reasoning, and multi-stage derivations based on this run.
- Keep GLM-5.2 in the candidate pool for executable algorithm generation.
- Treat
HTTP 200 + empty contentas a business failure. - Parse and validate JSON instead of accepting visually plausible output.
- Run generated code in an isolated test harness.
- Track first-delivery success separately from retry-assisted success.
FAQ#
Is GLM-5.3 universally better?#
No. It had better first-run coverage, but GLM-5.2 won the executable code task.
Did more output budget fix the failures?#
Not reliably. GLM-5.2 physics still returned an empty body at 20k. GLM-5.3 math remained empty at 20k, and its 24k code retry failed hidden tests.
Why count HTTP 200 responses as failures?#
Because multiple responses consumed the entire reasoning budget and delivered no usable content.
How was code graded?#
The original generated file was imported and executed against the same hidden harness. No manual fixes were allowed.
Was latency part of the score?#
No. It was kept as operational evidence only.
What is the practical model-selection rule?#
Route by task type and enforce real acceptance tests. A single aggregate model ranking loses the most important result from this benchmark.
Verdict#
GLM-5.3 won first-delivery coverage, 4/6 to 2/6. GLM-5.2 delivered the best executable algorithm. The defensible production conclusion is task-aware routing with strict validation, not automatic replacement of the older model.
Run the same models through Crazyrouter's OpenAI-compatible API.